NVIDIA GPU Server
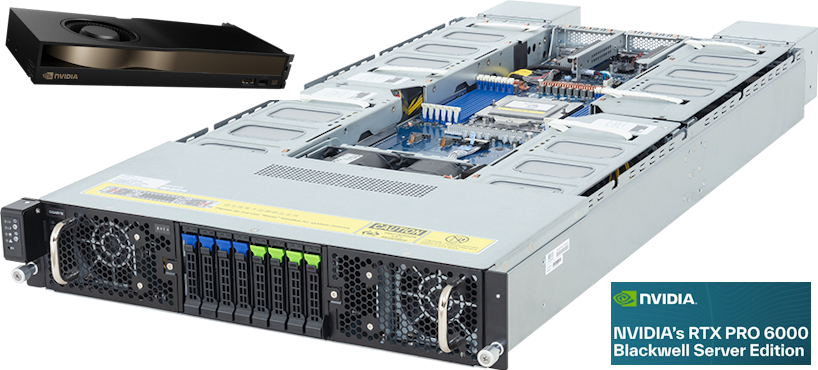
- NVIDIA RTX 6000 Blackwell Pro or comparable platform
- AMD EPYC or Ryzen Pro enterprise CPU platform
- DDR5 ECC memory and high-speed NVMe storage
- Ideal for AI inference, visualization and productive GPU workloads
- Suitable for dual GPU and larger AI node configurations
- Optimized for LLM training, HPC and GPU compute workloads
- Enterprise networking, backup and firewall options
- Designed for scalable AI infrastructure
Dedicated NVIDIA GPU Servers for AI and Compute Workloads
A dedicated NVIDIA GPU server provides exclusive access to physical GPU resources, CPU performance, memory and storage. This is a major advantage for AI hosting, machine learning pipelines, large language model workloads, 3D rendering, CAD applications and scientific compute jobs that require stable throughput and direct hardware control.
Unlike shared cloud GPU environments, dedicated GPU hosting from menkiSys is focused on predictable performance, isolated hardware resources and enterprise-ready operational stability. This makes these systems ideal for productive business AI and high-performance computing projects.
AI Hosting for LLM, Deep Learning, Inference and HPC
NVIDIA GPU server hosting is particularly suitable for artificial intelligence (AI), deep learning, neural network training, large language models (LLM), LLM inference, generative AI, chatbots, computer vision, scientific simulations and high-performance computing (HPC) workloads. Modern GPU architectures enable massive parallel processing capabilities that are essential for data-intensive machine learning and AI workloads. With powerful NVIDIA accelerator platforms such as the NVIDIA RTX 6000 Blackwell Pro (96 GB), RTX 5090, H100 or H200, organizations can run AI projects far more efficiently than on traditional CPU-only infrastructure. These GPUs are specifically optimized for AI model training, LLM workloads, deep learning frameworks, GPU rendering and large-scale data analytics, delivering exceptional memory bandwidth and computational performance for modern AI frameworks such as PyTorch, TensorFlow and CUDA-based applications. For companies, research institutions and AI startups working with generative AI, transformer models or large neural networks, dedicated NVIDIA GPU servers represent a critical performance factor. Workloads such as LLM training, AI inference clusters, computer vision pipelines, data science environments and GPU-accelerated simulation systems benefit significantly from dedicated AI servers powered by NVIDIA Blackwell RTX 6000 Pro or other high-end GPU architectures. These systems enable organizations to process large datasets in parallel, significantly reduce training times and deploy complex AI models into production environments much faster. Whether your use case involves model development, inference pipelines, data science platforms, GPU rendering, scientific simulations or enterprise analytics, menkiSys provides scalable GPU server hosting from Austria with professional support and a dedicated datacenter environment. Our infrastructure supports both single-GPU servers and multi-GPU configurations, including scalable AI clusters designed for demanding enterprise workloads. By combining dedicated bare-metal GPU servers with NVIDIA Blackwell RTX 6000 Pro accelerators, high-performance NVMe storage, ECC memory and redundant fiber network connectivity, businesses receive a stable and powerful platform for modern AI infrastructure, LLM hosting and GPU-accelerated high-performance applications.
Whether your use case is model development, inference pipelines, data science, rendering or enterprise analytics: menkiSys offers scalable GPU server hosting from Austria with professional support and a dedicated datacenter environment.
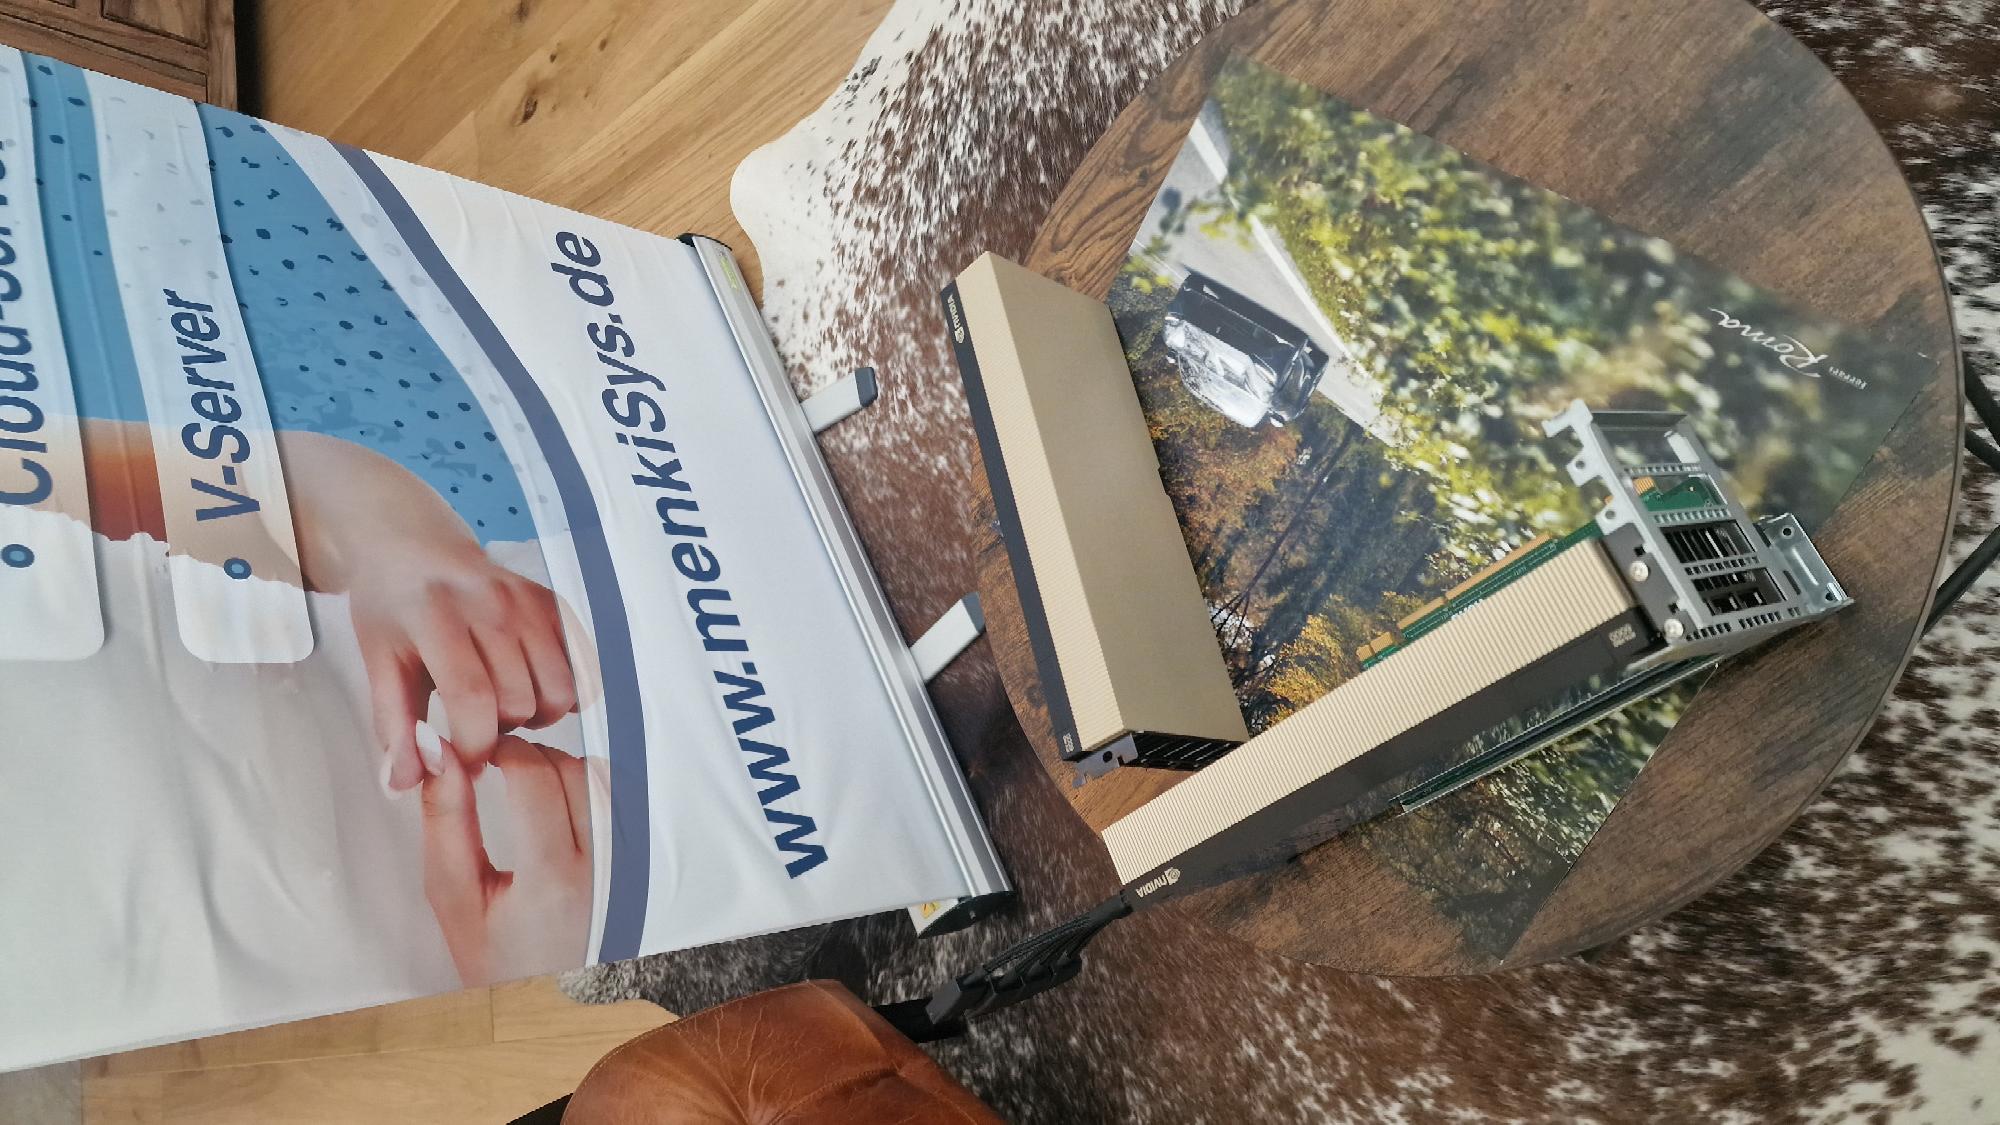
Rent NVIDIA B300 GPU Servers – Blackwell Ultra AI Hosting in Austria
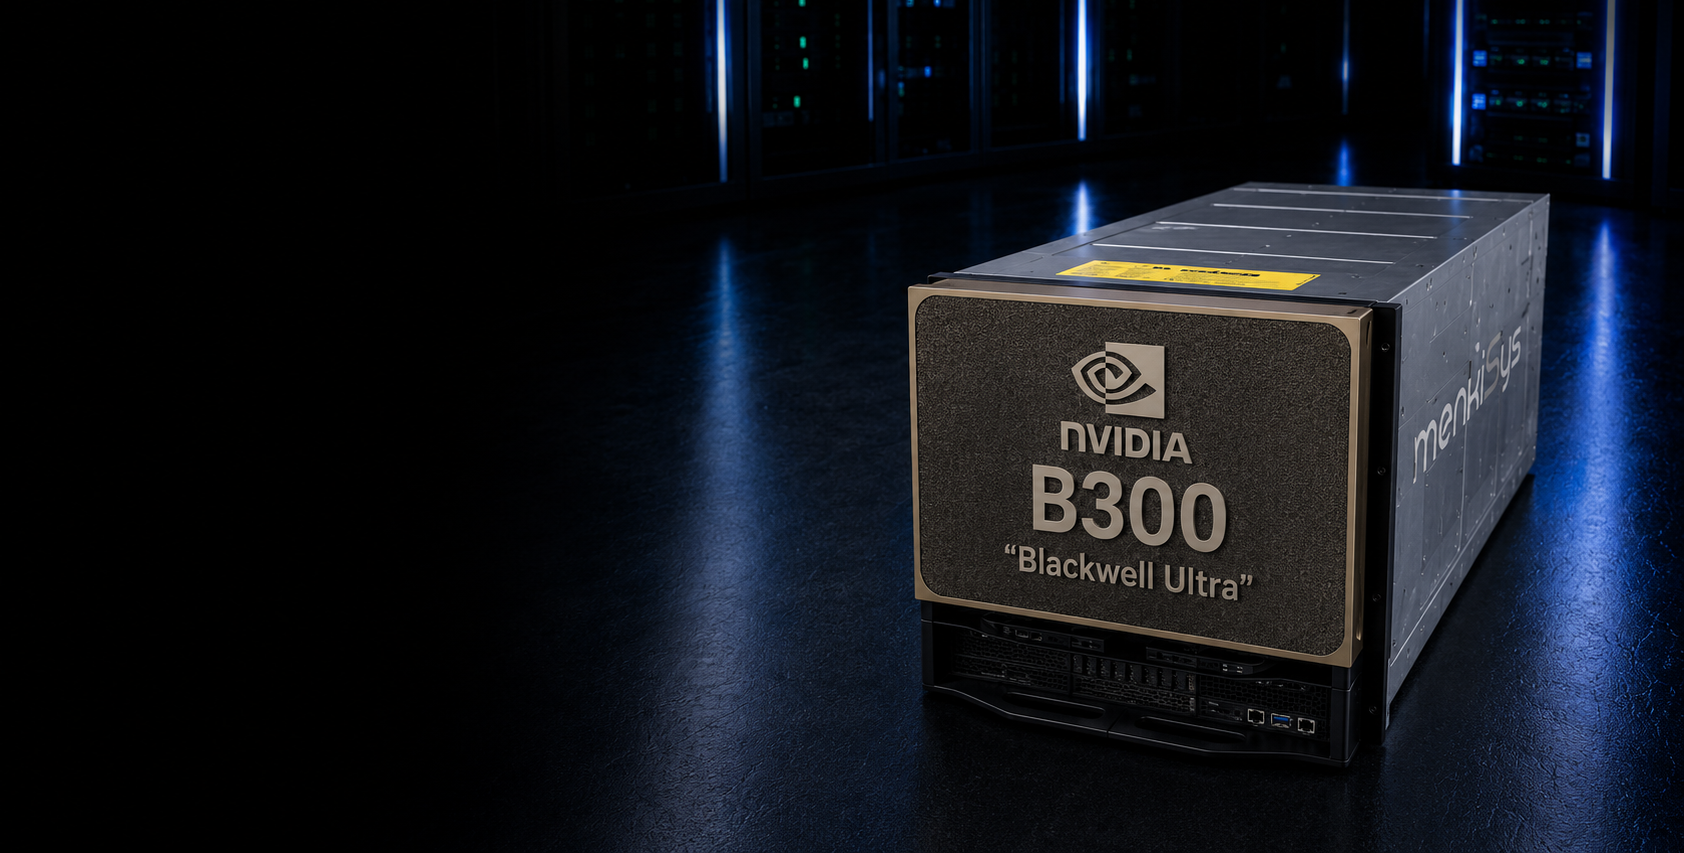
Looking to run large AI models on dedicated hardware with a hosting partner in Austria? A NVIDIA HGX B300 server solution from menkiSys addresses enterprises, AI startups and research teams with demanding compute, GPU memory and parallel processing requirements. The focus is on production large language models, generative AI and long-term infrastructure planning. Hardware configuration, operating arrangements and delivery are coordinated individually for your B300 project.
The HGX B300 platform connects eight NVIDIA Blackwell Ultra GPUs through fifth-generation NVLink and NVSwitch. HBM3e GPU memory and fast accelerator interconnects provide the foundation for demanding multi-GPU applications. This supports a dedicated AI environment that brings model serving, data processing and development workflows together.
LLM inference, reasoning and generative AI on NVIDIA B300
A NVIDIA B300 AI server is worth considering when large language models, long contexts or many concurrent requests put pressure on existing infrastructure. Potential applications include internal AI assistants, automated document processing, knowledge search, coding assistants and multimodal services. Planning considers model size alongside response-time targets, expected user numbers and output length. Together, these factors determine the resources required for dependable production operation.
Retrieval-augmented generation (RAG) also requires planning for document storage, embedding processing and search. The GPU handles suitable accelerated model computations, while answer quality also depends on the data, retrieval pipeline and application design. Reasoning models require capacity planning for longer computation sequences as well. The result is an infrastructure design based on the actual business workflow.
Fine-tuning, deep learning and distributed model training
Beyond inference, a B300 environment can be planned for AI model adaptation and development. This includes fine-tuning on company datasets, neural network experiments and distributed training runs. Whether full training, a parameter-efficient approach or a smaller GPU configuration is appropriate depends on the model, data and project budget. Clearly defined training objectives help determine the right server resources.
Multi-GPU workloads require software and model parallelism that match the hardware. Memory across multiple GPUs does not automatically become one freely usable pool for an application. Frameworks, model weight placement, intermediate results and communication overhead jointly determine usable capacity. Driver, CUDA and training or inference software versions therefore form part of project planning.
Dedicated B300 hosting in an Austrian datacenter
For businesses with specific location requirements, menkiSys provides a direct contact for GPU server hosting in Austria. For a B300 project at the Marchtrenk datacenter in Upper Austria, server location, access arrangements and service scope are defined in the quotation. Dedicated deployment provides exclusive use of the agreed hardware and a clear basis for capacity planning and internal operating processes.
Connectivity, storage, backups and support should match the AI project from the outset. Large training datasets require different data paths from an internal chatbot with moderate request volumes. Recovery requirements, maintenance windows and administrative access also vary. menkiSys coordinates these requirements with you to turn powerful GPU hardware into a server solution suited to your operations.
NVIDIA HGX B300 or RTX PRO: Which GPU platform fits?
Not every AI project needs eight B300 GPUs. For smaller models, development, visualization or individual inference services, a dedicated NVIDIA RTX PRO 6000 GPU server may be the more economical choice. NVIDIA HGX B300 becomes relevant when the workload benefits from a tightly connected multi-GPU platform. The deciding factor is your application’s performance at an appropriate level of resource consumption.
Rent an NVIDIA B300 server: Configuration and quotation
For a tailored quotation, tell us your AI model or application, whether you need training or inference, your anticipated memory requirements and target deployment date. Data volumes, concurrent users and the preferred contract term also help determine the configuration. Pricing, exact specifications and availability are confirmed for each project. This gives you a clear basis for deciding on an NVIDIA B300 GPU server from menkiSys.

Enterprise GPU Infrastructure from a Private Austrian Datacenter
Enterprise GPU Infrastructure from a Family-Owned Private Datacenter in Austria menkiSys operates its GPU and server infrastructure as a family-owned technology company based in Austria. In contrast to large anonymous cloud providers or global hosting corporations, menkiSys focuses on a personally managed company structure with direct technical responsibility, fast decision-making processes and long-term customer relationships. The entire infrastructure is operated in a privately managed datacenter in Upper Austria and is continuously expanded and optimized. This approach allows businesses to benefit from a stable enterprise GPU infrastructure, transparent operational processes and direct access to experienced technical specialists. Especially for complex AI workloads, GPU clusters, HPC projects and large language model environments, reliable infrastructure and direct support are essential. menkiSys combines modern NVIDIA GPU technologies – including RTX 6000 Blackwell Pro, RTX 5090, H100, H200 and upcoming B200 AI accelerators – with dedicated server hardware, redundant network architecture and professional datacenter standards. As a family-owned hosting provider, menkiSys places strong emphasis on long-term partnerships, technical transparency and sustainable infrastructure development. Customers therefore gain access not only to powerful GPU servers but also to a reliable hosting platform for artificial intelligence, deep learning, high-performance computing, simulation and data-intensive enterprise applications.
This makes menkiSys GPU servers highly suitable for enterprise AI projects, agency platforms, managed customer solutions, simulation workloads and dedicated compute services that require more than anonymous mass-market cloud hosting.
NVIDIA GPU Servers Explained
Key technical and business questions about dedicated AI GPU servers, enterprise GPU hosting and productive NVIDIA workloads
-
An NVIDIA GPU server is a dedicated high-performance server equipped with professional GPU accelerator hardware. These systems are designed for artificial intelligence, machine learning, LLM workloads, rendering, simulation and compute-intensive business applications.
-
Maximum compute performance: optimized for AI, deep learning, LLM and HPC.
Scalability: from single GPU systems to larger dedicated GPU environments.
Enterprise stability: dedicated hardware without shared cloud contention.
Professional deployment: suitable for productive business workloads and long-term infrastructure planning.
-
Typical workloads include large language models, AI inference, deep learning, computer vision, GPU rendering, simulation, research workloads, data science and high-performance computing.
-
menkiSys operates a private Austrian datacenter with a strong focus on enterprise hosting, direct support, fast response times and tailored infrastructure solutions. Instead of anonymous mass hosting, customers receive project-oriented support and a technically controlled environment for productive GPU workloads.
-
Yes. We analyze your planned workloads and recommend a suitable GPU server configuration based on project size, memory requirements, compute intensity and expected scalability. This ranges from single GPU server setups to more advanced dedicated AI environments.
-
Yes. menkiSys provides dedicated NVIDIA GPU servers in Austria for companies, AI projects, developers and professional compute workloads. The systems are operated in the menkiSys datacenter in Austria and can be configured for AI inference, large language models, deep learning, rendering, simulation and HPC. A dedicated GPU server gives the customer exclusive access to the agreed hardware resources and creates a predictable platform for productive workloads.
-
A dedicated GPU server provides reserved physical server resources for one customer, while many GPU cloud services are designed around virtualized or consumption-based resources. Dedicated systems are particularly attractive when workloads run continuously, predictable performance is required, large datasets remain permanently on the server or the customer wants direct control over the operating system, drivers and software stack. Cloud models can be useful for short or highly variable workloads, while dedicated GPU hosting is often easier to calculate for long-running production environments.
-
The right LLM GPU server depends on model size, quantization, context length, number of concurrent users and whether the system is intended for inference, fine-tuning or training. Professional RTX platforms can be suitable for many inference and development workloads, while high-end multi-GPU platforms such as NVIDIA HGX B300 target significantly larger AI workloads and scaling requirements. menkiSys therefore sizes AI server configurations according to the actual model and application instead of selecting a GPU solely by product name.
-
The required GPU VRAM for AI and LLM workloads cannot be determined from parameter count alone. Precision or quantization, context length, KV cache, batch size, framework overhead and concurrent requests all influence memory consumption. Training and fine-tuning can also require substantially more memory than pure inference. For this reason, menkiSys evaluates the planned model, software stack and expected usage pattern before recommending a GPU server configuration.
-
An NVIDIA HGX B300 server becomes relevant when an AI project requires a tightly integrated multi-GPU platform for very large models, demanding inference services, model training, fine-tuning or other high-performance AI workloads. The decisive factor is whether the application can actually benefit from multiple high-end GPUs and the associated system architecture. For smaller projects, a professional single-GPU or dual-GPU server can be more economical. menkiSys therefore compares the workload requirements before selecting the platform.
-
Yes. A professional NVIDIA RTX PRO GPU server can be a strong platform for AI inference, development environments, visualization, rendering, computer vision and many business AI applications. It is often a practical choice when a project requires dedicated GPU performance but does not need a large HGX multi-GPU system. CPU performance, system memory, NVMe storage and network connectivity should still be dimensioned together with the GPU so that the complete server platform matches the workload.
-
Yes. menkiSys can provide multi-GPU server configurations for workloads that benefit from more than one NVIDIA GPU. Typical use cases include larger LLM inference environments, distributed training, deep learning, rendering and scientific computing. The software must support an appropriate form of model, tensor or data parallelism because the memory of several GPUs does not automatically behave like one unrestricted memory pool. The server architecture is therefore planned together with the intended AI framework and workload.
-
Dedicated NVIDIA GPU servers can be deployed with common Linux distributions or suitable Windows Server environments, depending on the selected hardware, drivers and application. Typical AI stacks include NVIDIA drivers, CUDA-based frameworks, container environments and inference or training software. Applications such as PyTorch, TensorFlow, vLLM, Ollama or custom AI services can be evaluated according to the project requirements. Compatibility should always be checked against the exact GPU generation and required software versions.
-
A fast GPU alone does not guarantee a fast AI system. NVMe storage, system RAM, CPU performance and network bandwidth influence how quickly datasets, model files and application data can reach the GPU. Large training datasets and model checkpoints can generate substantial storage and network traffic, while preprocessing may place additional load on the CPU and memory subsystem. A balanced GPU server therefore avoids bottlenecks outside the accelerator and improves overall infrastructure efficiency.
-
GPU server hosting in Austria can be attractive for companies that want a clearly defined server location, direct technical contacts and infrastructure operated close to their business. A domestic datacenter can simplify internal requirements regarding server location, access concepts and operational responsibilities. menkiSys combines dedicated NVIDIA GPU hardware with datacenter operation in Austria and project-specific support, making it suitable for businesses that do not want to place every AI workload with an international hyperscaler.
